- Blog Categories
- Project Management
- Agile Management
- IT Service Management
- Cloud Computing
- Business Management
- BI And Visualisation
- Quality Management
- Cyber Security
- DevOps
- Most Popular Blogs
- PMP Exam Schedule for 2025: Check PMP Exam Date
- Top 60+ PMP Exam Questions and Answers for 2025
- PMP Cheat Sheet and PMP Formulas To Use in 2025
- What is PMP Process? A Complete List of 49 Processes of PMP
- Top 15+ Project Management Case Studies with Examples 2025
- Top Picks by Authors
- Top 170 Project Management Research Topics
- What is Effective Communication: Definition
- How to Create a Project Plan in Excel in 2025?
- PMP Certification Exam Eligibility in 2025 [A Complete Checklist]
- PMP Certification Fees - All Aspects of PMP Certification Fee
- Most Popular Blogs
- CSM vs PSM: Which Certification to Choose in 2025?
- How Much Does Scrum Master Certification Cost in 2025?
- CSPO vs PSPO Certification: What to Choose in 2025?
- 8 Best Scrum Master Certifications to Pursue in 2025
- Safe Agilist Exam: A Complete Study Guide 2025
- Top Picks by Authors
- SAFe vs Agile: Difference Between Scaled Agile and Agile
- Top 21 Scrum Best Practices for Efficient Agile Workflow
- 30 User Story Examples and Templates to Use in 2025
- State of Agile: Things You Need to Know
- Top 24 Career Benefits of a Certifed Scrum Master
- Most Popular Blogs
- ITIL Certification Cost in 2025 [Exam Fee & Other Expenses]
- Top 17 Required Skills for System Administrator in 2025
- How Effective Is Itil Certification for a Job Switch?
- IT Service Management (ITSM) Role and Responsibilities
- Top 25 Service Based Companies in India in 2025
- Top Picks by Authors
- What is Escalation Matrix & How Does It Work? [Types, Process]
- ITIL Service Operation: Phases, Functions, Best Practices
- 10 Best Facility Management Software in 2025
- What is Service Request Management in ITIL? Example, Steps, Tips
- An Introduction To ITIL® Exam
- Most Popular Blogs
- A Complete AWS Cheat Sheet: Important Topics Covered
- Top AWS Solution Architect Projects in 2025
- 15 Best Azure Certifications 2025: Which one to Choose?
- Top 22 Cloud Computing Project Ideas in 2025 [Source Code]
- How to Become an Azure Data Engineer? 2025 Roadmap
- Top Picks by Authors
- Top 40 IoT Project Ideas and Topics in 2025 [Source Code]
- The Future of AWS: Top Trends & Predictions in 2025
- AWS Solutions Architect vs AWS Developer [Key Differences]
- Top 20 Azure Data Engineering Projects in 2025 [Source Code]
- 25 Best Cloud Computing Tools in 2025
- Most Popular Blogs
- Company Analysis Report: Examples, Templates, Components
- 400 Trending Business Management Research Topics
- Business Analysis Body of Knowledge (BABOK): Guide
- ECBA Certification: Is it Worth it?
- Top Picks by Authors
- Top 20 Business Analytics Project in 2025 [With Source Code]
- ECBA Certification Cost Across Countries
- Top 9 Free Business Requirements Document (BRD) Templates
- Business Analyst Job Description in 2025 [Key Responsibility]
- Business Analysis Framework: Elements, Process, Techniques
- Most Popular Blogs
- Best Career options after BA [2025]
- Top Career Options after BCom to Know in 2025
- Top 10 Power Bi Books of 2025 [Beginners to Experienced]
- Power BI Skills in Demand: How to Stand Out in the Job Market
- Top 15 Power BI Project Ideas
- Top Picks by Authors
- 10 Limitations of Power BI: You Must Know in 2025
- Top 45 Career Options After BBA in 2025 [With Salary]
- Top Power BI Dashboard Templates of 2025
- What is Power BI Used For - Practical Applications Of Power BI
- SSRS Vs Power BI - What are the Key Differences?
- Most Popular Blogs
- Data Collection Plan For Six Sigma: How to Create One?
- Quality Engineer Resume for 2025 [Examples + Tips]
- 20 Best Quality Management Certifications That Pay Well in 2025
- Six Sigma in Operations Management [A Brief Introduction]
- Top Picks by Authors
- Six Sigma Green Belt vs PMP: What's the Difference
- Quality Management: Definition, Importance, Components
- Adding Green Belt Certifications to Your Resume
- Six Sigma Green Belt in Healthcare: Concepts, Benefits and Examples
- Most Popular Blogs
- Latest CISSP Exam Dumps of 2025 [Free CISSP Dumps]
- CISSP vs Security+ Certifications: Which is Best in 2025?
- Best CISSP Study Guides for 2025 + CISSP Study Plan
- How to Become an Ethical Hacker in 2025?
- Top Picks by Authors
- CISSP vs Master's Degree: Which One to Choose in 2025?
- CISSP Endorsement Process: Requirements & Example
- OSCP vs CISSP | Top Cybersecurity Certifications
- How to Pass the CISSP Exam on Your 1st Attempt in 2025?
- Most Popular Blogs
- Top 7 Kubernetes Certifications in 2025
- Kubernetes Pods: Types, Examples, Best Practices
- DevOps Methodologies: Practices & Principles
- Docker Image Commands
- Top Picks by Authors
- Best DevOps Certifications in 2025
- 20 Best Automation Tools for DevOps
- Top 20 DevOps Projects of 2025
- OS for Docker: Features, Factors and Tips
- More
- Agile & PMP Practice Tests
- Agile Testing
- Agile Scrum Practice Exam
- CAPM Practice Test
- PRINCE2 Foundation Exam
- PMP Practice Exam
- Cloud Related Practice Test
- Azure Infrastructure Solutions
- AWS Solutions Architect
- IT Related Pratice Test
- ITIL Practice Test
- Devops Practice Test
- TOGAF® Practice Test
- Other Practice Test
- Oracle Primavera P6 V8
- MS Project Practice Test
- Project Management & Agile
- Project Management Interview Questions
- Release Train Engineer Interview Questions
- Agile Coach Interview Questions
- Scrum Interview Questions
- IT Project Manager Interview Questions
- Cloud & Data
- Azure Databricks Interview Questions
- AWS architect Interview Questions
- Cloud Computing Interview Questions
- AWS Interview Questions
- Kubernetes Interview Questions
- Web Development
- CSS3 Free Course with Certificates
- Basics of Spring Core and MVC
- Javascript Free Course with Certificate
- React Free Course with Certificate
- Node JS Free Certification Course
- Data Science
- Python Machine Learning Course
- Python for Data Science Free Course
- NLP Free Course with Certificate
- Data Analysis Using SQL
AI Observability: What It Is, How It Works, Metrics, and Best Practices
Updated on Oct 15, 2026 | 0.6k+ views
Share:
Table of Contents
View all
Quick Overview
- AI observability helps teams understand AI system behavior by tracking model outputs, performance, errors, costs, and response quality.
- It helps detect incorrect AI responses, performance issues, rising operating costs, model drift, and potential safety risks.
- The four core pillars of AI observability are logs, metrics, traces, and AI evaluation, which help teams investigate problems and assess output quality.
- Key metrics include latency, error rate, token consumption, cost per request, answer relevance, groundedness, and safety violations.
- This guide covers how AI observability works, its core pillars, essential metrics, and practical steps to implement it in production.
Build practical skills to develop, deploy, and monitor AI agents with the Applied Agentic AI Certification Course. Learn how to create more reliable AI workflows and understand the role of observability in production AI systems.
Master the Right Skills & Boost Your Career
Avail your free 1:1 mentorship session
What is AI observability?
AI observability is the process of monitoring, analysing and understanding the behaviour of the AI application throughout its entire life cycle. It gives the team visibility into how the AI application is handling inputs, what outputs it is producing, how much it is consuming and how it is performing in the real world.
AI systems don't always produce the same output for the same input. There can be cases where an LLM, a recommendation engine or an AI agent will make some unexpected decision, give the wrong answer or behave in a different way as the data changes. AI observability helps the team to identify and understand such issues.
AI observability strategy tracks:
- User inputs and prompts
- Model responses
- System performance
- AI output quality
- Costs and resource usage
- Safety and compliance risks
Also Read: What Is AI Monitoring and Observability? A Simple Guide for Beginners
Why do AI systems need observability?
AI systems require observability in order to detect errors, maintain output quality, improve performance, manage costs and understand odd behaviour in production.
Detecting incorrect AI outputs
The main problem with AI systems is that they can give the wrong answer or some form of misleading information and still be confident in that answer. Those are the classic 'hallucinations'.
With the help of AI observability companies will be able to track response quality, identify bad outputs and investigate the root cause of any error. They will be able to fix the problem before any damage is done.
Improving performance and reliability
Poor response times, failed requests and unreliable workflows can all have a negative impact on the user experience. AI observability is key to diagnosing performance and reliability problems.
Continuous monitoring enables organisations to deliver a better AI experience with faster response times and greater reliability.
Controlling AI operating costs
Operating costs of running AI models (particularly LLMs) can be quite high due to excessive use of tokens, unnecessary requests, and inefficient workflows.
AI observability enables organizations to track their resource usage and understand the sources of their costs. It enables them to spend efficiently without having to compromise on performance.
Identifying model and data drift
The AI models are trained on historical data and that doesn't guarantee that the future data will be any similar to that historical data. Drift in the new data could well reduce the efficiency of the model.
AI observability makes it easier to detect both types of drift and to take action before the quality has degraded too much.
Strengthening AI safety and security
It's absolutely vital that organizations ensure the output of an AI system is safe, ethical and compliant with the relevant regulations. Observability enables you to spot inappropriate content, accidental data leakage, prompt injection attempts and all sorts of other threats.
Also Read: AI Observability Tools: What DevOps Teams Need to Know
What are the core pillars of AI observability?
AI observability uses application telemetry combined with specific AI evaluation signals to monitor system performance, model behaviour and output quality. The key elements of AI observability are:
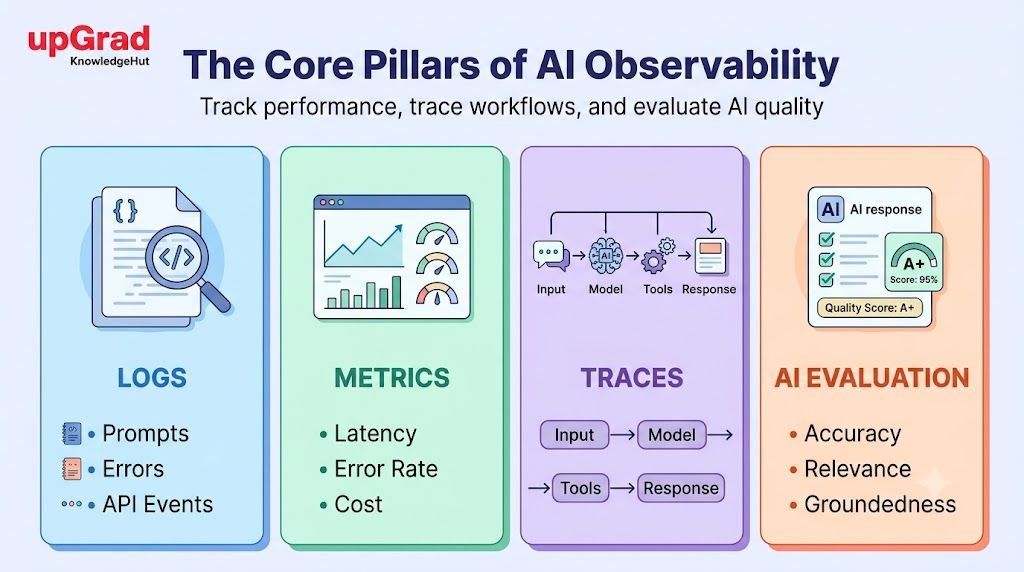
1. Logs
Logs contain detailed information about what happens inside an AI application. These can be prompts, responses, models, API requests, errors, and other system events. Without proper logging, it would be much harder to diagnose any problems with AI.
Logs help teams:
- Investigate incidents
- Review historical activity
- Troubleshoot failures
- Support auditing requirements
2. Metrics
Metrics are the quantitative side of AI observability. They enable a team to see how the AI system is performing. They're used to identify trends, measure progress and spot anomalous behaviour.
Examples include:
- Response latency
- Error rates
- Token consumption
- Accuracy scores
- Cost per request
3. Traces
Traces show the full journey of a request through the AI app. They connect the input, the prompt, the retrieval, the model call, the agent action and the response.
Traces help in identifying where the failure is and the interaction between the various components within the system.
4. AI evaluation and quality monitoring
The monitoring systems that are used in traditional systems will tell you whether the system is running or not, but they won't tell you whether an AI generated response is relevant or correct.
AI evaluation measures output quality using factors such as:
- Accuracy
- Relevance
- Groundedness
- Hallucination rates
- User satisfaction
Learn to build and manage AI-driven products with the AI-Powered Product Management Certification with Microsoft. Understand how to evaluate AI performance, improve product quality, and align AI solutions with business goals.
How does AI observability work?
AI observability works by gathering information across the AI application, linking together the relevant events, assessing the outcomes and then using that to improve the system.
1. Collect data across the AI workflow
The first step is to gather useful information from the various parts of the application. This could be user requests, model calls, documents retrieved, API activity, agent actions and infrastructure performance.
The data collected should be appropriate for the application. A predictive model will require input stats and output predictions. A generative AI application will also require prompt, response and token data.
2. Trace requests end to end
Next the teams link up the events via traces. That enables them to trace a request from the point of entry all the way through to the final outcome.
For instance if the AI assistant gives an incomplete answer the trace might show that the retrieval system only returned part of the information that was required.
3. Monitor performance, quality, and cost metrics
Teams then go on to track the metrics that are important to their application (response time, failure rates, model usage, output quality etc).
Monitoring those signals in conjunction helps the team to understand the trade-offs. A cheaper model may well save money but could also result in less accurate answers.
4. Evaluate AI outputs continuously
AI applications should be tested after deployment rather than just prior to release. You can take production samples, assess them against your quality criteria and then compare the results across different model versions or application changes. For high risk decisions automated checks may require further human review.
5. Detect anomalies and generate alerts
Alerting systems will alert the team if a metric goes outside of its acceptable range or if a suspicious pattern is detected.
For example an unexpected spike in failed requests, token usage or unsafe outputs might trigger an alert. The thresholds would of course be based on what is normal for the application and the business requirements.
6. Enable root-cause analysis and optimization
When an issue arises teams will use the logs, traces, metrics and evaluation results to root cause it. They can then fix the issue, make a change, test the change and see if performance has improved.
This is a continual improvement cycle rather than just relying on user complaints to find out about every problem.
Also Read: AI Observability for Enterprise Teams: What It Is and Why It Matters
Which metrics should you track in AI observability?
Not every metric has the same value. The best approach is to focus on performance, cost, quality, and safety metrics that directly affect business outcomes.
Performance metrics
Performance metrics help determine the efficiency of the AI system performance.
- Latency: The amount of time taken to respond to a request.
- Throughput: The number of requests a system can handle within a specific period.
- Error rate: Percentage of requests that fail due to system/application failures.
Cost metrics
Cost metrics enable organizations to control the cost of AI operations.
- Token usage: The number of input/output tokens handled by AI models.
- Cost per request: Average cost spent on handling each request.
- Model usage: Monitoring the frequency of using specific models and their costs.
Quality metrics
Quality metrics help assess the relevance and reliability of the output generated.
- Hallucination rate: Number of times a model produces inaccurate/false information.
- Answer relevance: Assesses the ability of responses to solve the user’s question.
- Groundedness: How aligned responses are with trusted source data.
- Accuracy: How accurate the output is regarding factual correctness.
- Safety metrics: Safety metrics ensure the responsible performance of AI systems.
- Toxicity: Harmful/Offensive content generated by an AI system.
- PII exposure: Detection of accidental revelation of personal information.
- Policy violations: Outputs that violate organizational or policy requirements.
Build a stronger foundation in data science and applied AI to better understand model performance, data quality, and the challenges of maintaining reliable AI systems with the Executive Post Graduate Certificate in Data Science and Applied AI.
How to implement AI observability in production?
It is not necessary to monitor every possible signal from day one. Instead, start by addressing the most significant risks and then expand the scope as the application develops.
1. Define observability goals
Determine what the team needs to know in order to improve. For example, a customer support assistant might focus on answer quality, response time, and cost, while a fraud detection model might concentrate on prediction performance and changes in the incoming data. Wherever possible, set specific targets.
2. Instrument the AI application
Make sure that the necessary instrumentation is added in order to obtain information from the model calls, the APIs, the retrieval systems, and the supporting infrastructure.
Tools and standards like OpenTelemetry can assist teams in gathering and linking together telemetry data from the various components that are supported. You should select an approach that is suitable for the technology stack already in use.
3. Set up quality evaluations
Prepare some test cases and evaluation criteria that are based on actual user requests, and keep record of any errors, relevance, groundedness, and task success where this is appropriate.
You should regularly review the samples since automated evaluations may fail to detect some errors or may give misleading results.
4. Configure alerts and dashboards
Create dashboards that combine key performance, quality, cost, and safety indicators and set up alerts only for significant changes rather than for every minor fluctuation.
Make sure to put in appropriate access controls, data redaction, and retention policies in order to protect sensitive information.
5. Investigate issues and improve continuously
On seeing an alert, use the telemetry that is available to identify the probable cause, carry out the repair, test the change and then compare the results with past performance.
For instance, should an AI assistant begin to give irrelevant answers, the team could check the documents that were retrieved, look at the model's outputs, and make adjustments to the retrieval process if necessary.
The goal is to incorporate observability into the usual development and maintenance processes so that teams can pick up on problems early on and improve the AI systems based on evidence not by guessing.
Also Read: What Is Observability in DevOps? Tools and Best Practices
Conclusion
AI observability helps teams understand how AI systems behave after deployment and identify issues before they affect more users. By tracking logs, metrics, traces, and output quality, teams can detect errors, improve reliability, and control operating costs.
Monitoring model behavior, data changes, and safety risks also helps maintain consistent results over time. A well-planned AI observability approach allows teams to investigate problems using real evidence and make informed improvements.
Have A Query? Get in Touch With Our Customer Support | upGrad KnowledgeHut
Frequently Asked Questions (FAQs)
1. What is AI observability in production?
AI observability in production is the process of tracking an AI application's behavior after it is deployed. It collects data about model inputs and outputs, response times, errors, costs, and output quality. This helps teams identify issues such as incorrect predictions, failed API calls, and unreliable AI responses.
2. Why is AI observability important?
AI observability helps teams detect incorrect outputs, investigate performance issues, track model costs, and identify changes in data or model behavior. It also helps monitor potential safety risks, such as harmful responses or sensitive information exposure. Without it, an application may appear healthy while producing poor results.
3. How does observability detect AI failures?
Observability detects AI failures by analyzing logs, metrics, traces, and evaluation results. For example, traces can reveal failed API calls or irrelevant documents retrieved by a RAG system, while quality evaluations can flag inaccurate answers. Teams use these signals to identify the likely cause and fix the problem.
4. What is the difference between AI observability and traditional monitoring?
Traditional monitoring tracks signals such as uptime, CPU usage, response time, and error rates to identify operational problems. AI observability also examines model behavior, output quality, prompt execution, retrieval results, and AI-specific risks. This helps teams identify issues such as incorrect answers even when the application is running normally.
5. Is AI observability the same as LLM observability?
No. LLM observability focuses on applications that use large language models, including prompt execution, generated responses, token usage, and hallucinations. AI observability has a broader scope and can also cover traditional machine learning models, predictive systems, and AI agents.
6. How do you measure hallucinations in production?
Teams measure hallucinations by evaluating AI-generated answers against trusted sources, retrieved documents, or verified reference answers. Automated evaluators can flag unsupported claims, while human reviewers can validate uncertain results. Teams should define a consistent evaluation method and track the percentage of responses flagged as hallucinations over time.
7. What are the best AI observability tools?
Popular options include Arize Phoenix, LangSmith, Langfuse, and Datadog LLM Observability. Arize Phoenix and Langfuse offer open-source options, while LangSmith provides tracing and evaluation capabilities, and Datadog connects LLM observability with broader application monitoring. The best choice depends on required integrations, deployment preferences, evaluation features, privacy needs, and budget.
8. How does OpenTelemetry support AI observability?
OpenTelemetry provides standard methods for collecting and exporting telemetry, including traces, metrics, and logs, from supported applications and services. It helps teams connect AI-related operations with the wider application infrastructure. AI-specific details, such as output quality and hallucination evaluations, may require additional instrumentation or evaluation tools.
9. What are the challenges of AI observability?
Key challenges include measuring subjective output quality, handling non-deterministic responses, tracing complex AI agent workflows, and controlling telemetry costs. Collecting prompts and responses can also expose sensitive information. Teams need suitable evaluation methods, clear data-retention policies, and instrumentation that provides useful visibility without collecting unnecessary data.
10. How can teams monitor AI quality and protect sensitive data?
Teams can monitor AI quality by evaluating accuracy, relevance, groundedness, and task success against defined criteria. To protect sensitive data, they should redact personally identifiable information, restrict access to logs and traces, encrypt stored data, and set retention limits. They should also review evaluation results regularly and avoid storing full prompts or responses unless necessary.
1648 articles published
KnowledgeHut is an outcome-focused global ed-tech company. We help organizations and professionals unlock excellence through skills development. We offer training solutions under the people and proces...
Get Free Consultation
By submitting, I accept the T&C and
Privacy Policy