- Blog Categories
- Project Management
- Agile Management
- IT Service Management
- Cloud Computing
- Business Management
- BI And Visualisation
- Quality Management
- Cyber Security
- DevOps
- Most Popular Blogs
- PMP Exam Schedule for 2026: Check PMP Exam Date
- Top 60+ PMP Exam Questions and Answers for 2026
- PMP Cheat Sheet and PMP Formulas To Use in 2026
- What is PMP Process? A Complete List of 49 Processes of PMP
- Top 15+ Project Management Case Studies with Examples 2026
- Top Picks by Authors
- Top 170 Project Management Research Topics
- What is Effective Communication: Definition
- How to Create a Project Plan in Excel in 2026?
- PMP Certification Exam Eligibility in 2026 [A Complete Checklist]
- PMP Certification Fees - All Aspects of PMP Certification Fee
- Most Popular Blogs
- CSM vs PSM: Which Certification to Choose in 2026?
- How Much Does Scrum Master Certification Cost in 2026?
- CSPO vs PSPO Certification: What to Choose in 2026?
- 8 Best Scrum Master Certifications to Pursue in 2026
- Safe Agilist Exam: A Complete Study Guide 2026
- Top Picks by Authors
- SAFe vs Agile: Difference Between Scaled Agile and Agile
- Top 21 Scrum Best Practices for Efficient Agile Workflow
- 30 User Story Examples and Templates to Use in 2026
- State of Agile: Things You Need to Know
- Top 24 Career Benefits of a Certifed Scrum Master
- Most Popular Blogs
- ITIL Certification Cost in 2026 [Exam Fee & Other Expenses]
- Top 17 Required Skills for System Administrator in 2026
- How Effective Is Itil Certification for a Job Switch?
- IT Service Management (ITSM) Role and Responsibilities
- Top 25 Service Based Companies in India in 2026
- Top Picks by Authors
- What is Escalation Matrix & How Does It Work? [Types, Process]
- ITIL Service Operation: Phases, Functions, Best Practices
- 10 Best Facility Management Software in 2026
- What is Service Request Management in ITIL? Example, Steps, Tips
- An Introduction To ITIL® Exam
- Most Popular Blogs
- A Complete AWS Cheat Sheet: Important Topics Covered
- Top AWS Solution Architect Projects in 2026
- 15 Best Azure Certifications 2026: Which one to Choose?
- Top 22 Cloud Computing Project Ideas in 2026 [Source Code]
- How to Become an Azure Data Engineer? 2026 Roadmap
- Top Picks by Authors
- Top 40 IoT Project Ideas and Topics in 2026 [Source Code]
- The Future of AWS: Top Trends & Predictions in 2026
- AWS Solutions Architect vs AWS Developer [Key Differences]
- Top 20 Azure Data Engineering Projects in 2026 [Source Code]
- 25 Best Cloud Computing Tools in 2026
- Most Popular Blogs
- Company Analysis Report: Examples, Templates, Components
- 400 Trending Business Management Research Topics
- Business Analysis Body of Knowledge (BABOK): Guide
- ECBA Certification: Is it Worth it?
- Top Picks by Authors
- Top 20 Business Analytics Project in 2026 [With Source Code]
- ECBA Certification Cost Across Countries
- Top 9 Free Business Requirements Document (BRD) Templates
- Business Analyst Job Description in 2026 [Key Responsibility]
- Business Analysis Framework: Elements, Process, Techniques
- Most Popular Blogs
- Best Career options after BA [2026]
- Top Career Options after BCom to Know in 2026
- Top 10 Power Bi Books of 2026 [Beginners to Experienced]
- Power BI Skills in Demand: How to Stand Out in the Job Market
- Top 15 Power BI Project Ideas
- Top Picks by Authors
- 10 Limitations of Power BI: You Must Know in 2026
- Top 45 Career Options After BBA in 2026 [With Salary]
- Top Power BI Dashboard Templates of 2026
- What is Power BI Used For - Practical Applications Of Power BI
- SSRS Vs Power BI - What are the Key Differences?
- Most Popular Blogs
- Data Collection Plan For Six Sigma: How to Create One?
- Quality Engineer Resume for 2026 [Examples + Tips]
- 20 Best Quality Management Certifications That Pay Well in 2026
- Six Sigma in Operations Management [A Brief Introduction]
- Top Picks by Authors
- Six Sigma Green Belt vs PMP: What's the Difference
- Quality Management: Definition, Importance, Components
- Adding Green Belt Certifications to Your Resume
- Six Sigma Green Belt in Healthcare: Concepts, Benefits and Examples
- Most Popular Blogs
- Latest CISSP Exam Dumps of 2026 [Free CISSP Dumps]
- CISSP vs Security+ Certifications: Which is Best in 2026?
- Best CISSP Study Guides for 2026 + CISSP Study Plan
- How to Become an Ethical Hacker in 2026?
- Top Picks by Authors
- CISSP vs Master's Degree: Which One to Choose in 2026?
- CISSP Endorsement Process: Requirements & Example
- OSCP vs CISSP | Top Cybersecurity Certifications
- How to Pass the CISSP Exam on Your 1st Attempt in 2026?
- Most Popular Blogs
- Top 7 Kubernetes Certifications in 2026
- Kubernetes Pods: Types, Examples, Best Practices
- DevOps Methodologies: Practices & Principles
- Docker Image Commands
- Top Picks by Authors
- Best DevOps Certifications in 2026
- 20 Best Automation Tools for DevOps
- Top 20 DevOps Projects of 2026
- OS for Docker: Features, Factors and Tips
- More
- Agile & PMP Practice Tests
- Agile Testing
- Agile Scrum Practice Exam
- CAPM Practice Test
- PRINCE2 Foundation Exam
- PMP Practice Exam
- Cloud Related Practice Test
- Azure Infrastructure Solutions
- AWS Solutions Architect
- IT Related Pratice Test
- ITIL Practice Test
- Devops Practice Test
- TOGAF® Practice Test
- Other Practice Test
- Oracle Primavera P6 V8
- MS Project Practice Test
- Project Management & Agile
- Project Management Interview Questions
- Release Train Engineer Interview Questions
- Agile Coach Interview Questions
- Scrum Interview Questions
- IT Project Manager Interview Questions
- Cloud & Data
- Azure Databricks Interview Questions
- AWS architect Interview Questions
- Cloud Computing Interview Questions
- AWS Interview Questions
- Kubernetes Interview Questions
- Web Development
- CSS3 Free Course with Certificates
- Basics of Spring Core and MVC
- Javascript Free Course with Certificate
- React Free Course with Certificate
- Node JS Free Certification Course
- Data Science
- Python Machine Learning Course
- Python for Data Science Free Course
- NLP Free Course with Certificate
- Data Analysis Using SQL
LLM Tokenization Explained: How It Works and Why It Matters for Product Managers
Updated on Oct 16, 2026 | 419 views
Share:
Table of Contents
View all
Quick Overview
- LLM tokenization is the process of breaking text into smaller units called tokens and converting them into numerical IDs that a large language model can process.
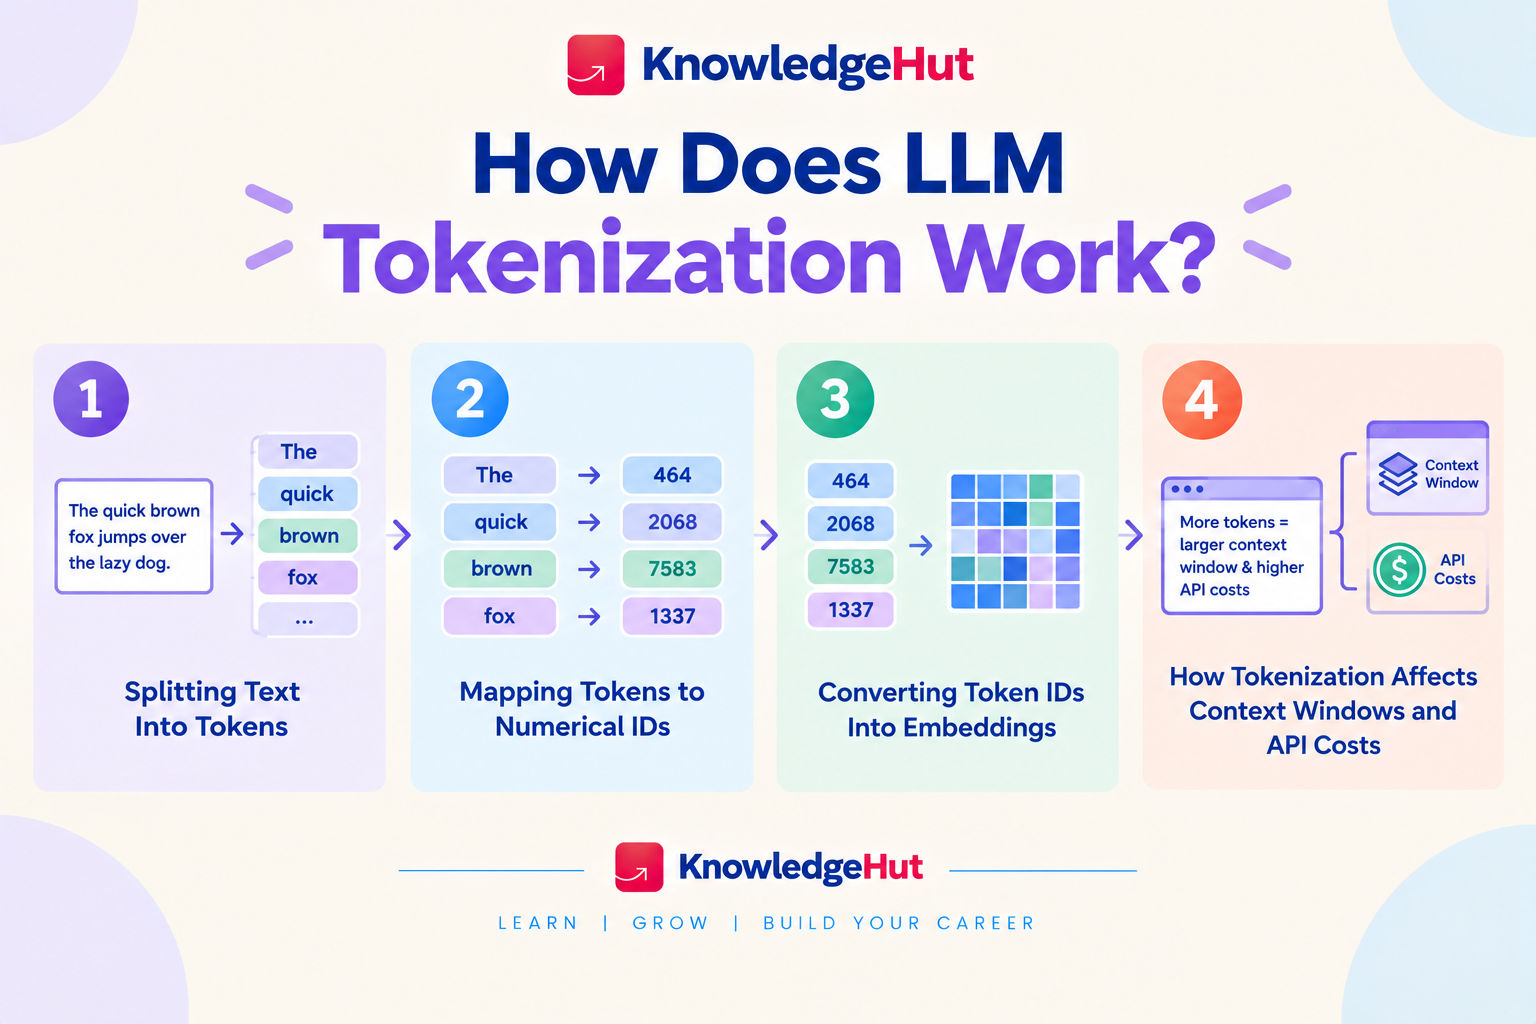
- How LLM Tokenization Works: The process involves splitting text into tokens, mapping them to numerical IDs, converting IDs into embeddings, and preparing the model to generate responses.
- Types and Algorithms of Tokenization: Word, character, and subword tokenization use different approaches to represent text. Common algorithms and frameworks include Byte Pair Encoding (BPE), WordPiece, and SentencePiece.
- Why Tokenization Matters for Product Managers: Token counts affect API costs, context window limits, response speed, multilingual performance, and the amount of information an AI feature can process.
- This guide explains how LLM tokenization works, its types and algorithms, and how product managers can use tokenization knowledge to estimate costs, manage context limits, and improve AI product experiences.
Product managers looking to understand how AI systems handle complex tasks can explore Applied Agentic AI to learn how AI agents use language models, tools, and multi-step workflows to deliver practical business outcomes.
What is LLM tokenization?
LLM tokenization is the process of breaking text into smaller units called tokens so that a large language model (LLM) can process and understand it. These tokens can represent complete words, parts of words, individual characters, or groups of bytes.
Before an LLM can work with a user prompt, it must convert the text into a format the model can process. Tokenization makes this possible by turning text into numerical identifiers that the model can use to generate a response.
For product managers, understanding LLM tokenization is useful when planning AI features, estimating API costs, managing context limits, and improving the user experience.
How does LLM tokenization convert text into token IDs?
LLM tokenization follows a sequence of steps that transforms human language into a format a model can process. Each step plays a role in how the model receives input and generates output.
- Splitting text into tokens: The tokenizer breaks the input into smaller units based on its vocabulary and tokenization method.
- Mapping tokens to numerical IDs: Each token is assigned an identifier from the tokenizer's vocabulary.
- Preparing model input: The token IDs are passed into the model, where they are converted into numerical representations called embeddings.
- Generating a response: The model processes these representations and predicts the next tokens to produce an answer.
Also read: How LLM Evaluation Works
Why do LLMs need tokenization?
Large language models cannot process raw text in the same way humans read it. They rely on numerical data to identify patterns, understand relationships between words, and generate language.
LLM tokenization helps bridge this gap by converting text into manageable units.
Its main purposes include:
- Making text machine readable: Converts words and other text elements into numerical identifiers.
- Handling unfamiliar words: Subword and byte based approaches can represent words that are not stored as complete vocabulary entries.
- Supporting multiple languages: Suitable tokenizers can process text across languages, although token efficiency varies.
- Managing computational resources: Token counts influence how much input and output a model processes.
- Supporting consistent processing: A tokenizer applies defined rules when converting text into tokens.
Product managers looking to deepen their understanding of LLMs can explore the PG Certificate in Applied Generative Engineering & LLM Applications to learn how large language models power AI applications and how to build, evaluate, and deploy them effectively.
How does LLM tokenization work?
LLM tokenization generally involves converting text into tokens, assigning numerical IDs, and preparing those IDs for the model. Although the exact implementation differs across models, the overall process follows a similar pattern.
Understanding these stages helps product managers identify why two models may process the same prompt differently in terms of token usage and cost.
1. Splitting text into tokens
The tokenizer first divides the input text into smaller units. Depending on the tokenization method, a unit might be a complete word, part of a word, a punctuation mark, or a byte based sequence.
The tokenizer does not necessarily split text in spaces. A long or uncommon word may become several tokens, while a familiar word may be represented by a single token.
The number of tokens depends on factors such as:
- The tokenization algorithm
- The vocabulary used by the tokenizer
- The language and writing system
- The presence of punctuation, symbols, or unusual text
2. Mapping tokens to numerical IDs
After splitting the text, the tokenizer assigns each token a numerical ID from its vocabulary. These IDs allow the model to work with text as structured numerical input.
The IDs are not meaningful scores or rankings. They are identifiers that help the model locate the corresponding entries in its vocabulary.
A model and its tokenizer must be compatible. Using an incorrect tokenizer can lead to unexpected token counts or input that does not match the model's expected representation.
3. Converting token IDs into embeddings
Once token IDs are prepared, the model maps them to numerical vectors called embeddings. These vectors provide representations that the model can use to learn and process relationships between tokens.
The model also uses positional information to account for the order of tokens in a sequence. This matters because the meaning of a sentence can change when its word order changes.
Tokenization and embeddings are related but distinct processes. Tokenization creates discrete units and IDs, while embeddings represent those IDs as vectors for model processing.
4. How tokenization affects context windows and API costs
Token counts directly influence how much text an LLM can process within its context window. The context window is the limit on the amount of input and other supported context a model can handle in a single request.
Tokenization also affects API pricing because many providers calculate charges using input and output tokens.
Product managers should consider the following factors:
- Input length: Longer prompts and documents generally use more tokens.
- Output length: Detailed responses can increase output token usage and cost.
- Context limits: System instructions, conversation history, retrieved documents, and the requested response may all use the available context.
- Language efficiency: Some languages require more tokens than others to express the same information.
- Repeated content: Long instructions and unnecessary context can increase token consumption across requests.
Also read: LLM Engineer Salary in India
What are the different types of LLM tokenization?
LLM tokenization methods differ in how they divide text. Word and character tokenization use straightforward units, while subword tokenization breaks text into smaller pieces when needed.
The choice affects vocabulary size, how unfamiliar words are handled, and how efficiently text is represented.
1. Word tokenization
Word tokenization divides text into individual words or word like units. Spaces and punctuation often help determine where one unit ends and another begins.
Its main advantage is simplicity. However, a vocabulary containing complete words can become very large, particularly when it needs to cover multiple languages, word forms, and uncommon terms.
Key limitations include:
- Unfamiliar words may not exist in the vocabulary.
- Different forms of the same word may require separate entries.
- Languages without spaces between words can require additional segmentation rules.
- Large vocabularies can increase the complexity of managing token representations.
2. Character tokenization
Character tokenization splits text into individual characters or character units. This approach can represent unfamiliar words without requiring every complete word to appear in the vocabulary.
It generally uses a smaller vocabulary than word based tokenization. However, a sentence may require many character tokens, increasing the sequence length the model must process.
Its main characteristics include:
- A relatively small vocabulary
- Flexible handling of new words and spelling variations
- Longer token sequences for ordinary text
- Greater processing demands when representing the same amount of text
3. Subword tokenization
Subword tokenization breaks text into units that can be smaller than a word but larger than a character. Common words may remain whole, while less familiar words can be divided into multiple pieces.
This approach balances vocabulary size and sequence length. It is widely used in modern language models because it can handle many word forms without storing every possible word as a separate vocabulary entry.
Its main benefits include:
- Efficient representation of common words
- Flexible handling of unfamiliar or compound words
- A manageable vocabulary size
- Support for varied text and word forms
Also read: How AI Teams Test and Validate LLM Outputs
What are the common LLM tokenization algorithms?
Several algorithms are used to build token vocabularies and determine how text is divided. Byte Pair Encoding, WordPiece, and SentencePiece are important approaches, although their training procedures and segmentation rules differ.
Product managers do not need to implement these algorithms themselves. Knowing the differences can help when comparing models, checking multilingual performance, and estimating token usage.
1. Byte Pair Encoding (BPE)
Byte Pair Encoding is a subword tokenization algorithm that builds a vocabulary by repeatedly merging frequently occurring adjacent units during training. The process starts with smaller units and combines them into larger units according to the learned merge rules.
BPE is used in several widely known language model tokenizers, although implementations can differ in their starting units and other details.
Its main features include:
- Building larger tokens from frequently occurring sequences
- Representing common text efficiently
- Breaking less familiar words into smaller units
- Using learned merge rules to segment text consistently
2. WordPiece
WordPiece is a subword tokenization method associated with models such as BERT. It builds a vocabulary of useful word pieces and uses that vocabulary to segment text into known units.
Unlike standard BPE, WordPiece uses a different vocabulary learning objective. Its segmentation procedure selects pieces according to the method's learned scoring and vocabulary rules.
Important characteristics include:
- Representing words with reusable subword units
- Handling many unfamiliar words through combinations of known pieces
- Keeping the vocabulary smaller than a complete word based vocabulary would require
- Supporting language processing tasks that benefit from subword representations
3. SentencePiece
SentencePiece is a tokenizer training and segmentation framework that can work directly from raw text without requiring pre-tokenized words. It is designed to support different languages and writing systems, including languages that do not consistently use spaces to separate words.
SentencePiece commonly supports algorithms such as BPE and Unigram Language Model tokenization. This makes it a framework for building tokenizers rather than a single segmentation algorithm.
Its key features include:
- Processing raw text without relying on conventional word boundaries
- Supporting multilingual text
- Providing configurable vocabulary and segmentation approaches
- Helping create consistent tokenization pipelines across different languages
Conclusion
LLM tokenization helps product managers understand how AI models process text, manage context limits, and calculate API costs. It also influences response efficiency and support for different languages.
When comparing LLMs, teams should consider token usage, model compatibility, language support, and pricing. The right choice depends on the product’s needs, budget, and expected performance, ensuring a balance between cost efficiency and a reliable user experience.
Have A Query? Get in Touch With Our Customer Support | upGrad KnowledgeHut
Frequently Asked Questions (FAQs)
1. What does tokenization do in LLMs?
LLM tokenization breaks text into smaller units called tokens, which can represent words, parts of words, or characters. These tokens are converted into numerical IDs that the model can process. This helps an LLM interpret input and generate responses.
2. How many words are 10,000 tokens?
The number of words in 10,000 tokens depends on the language, text structure, and tokenizer. For typical English text, 10,000 tokens may represent approximately 7,000 to 7,500 words. This is only an estimate, so actual counts can vary.
3. What are LLM tokens used for?
LLM tokens help models process user prompts, documents, and conversation history. They also determine how much text fits into a model’s context window. Token counts are important for managing API usage, response length, and AI application costs.
4. Why do LLMs use tokens instead of words?
Words alone are not flexible enough to represent every possible word, spelling, or language efficiently. LLM tokenization allows models to use complete words alongside smaller text units. This helps balance vocabulary size, processing efficiency, and the ability to handle unfamiliar words.
5. What are the three main types of tokenization?
The three commonly discussed types are word tokenization, character tokenization, and subword tokenization. Word tokenization splits text into words, while character tokenization uses individual characters. Subword tokenization breaks words into smaller units and is widely used in modern LLMs.
6. How does an LLM tokenize text?
An LLM tokenizer splits text into tokens using a defined vocabulary and algorithm. It then maps each token to a numerical ID, which the model converts into embeddings for processing. The exact token sequence depends on the tokenizer and the input text.
7. How much do LLM tokens cost?
LLM token costs depend on the provider, model, and whether tokens are used for input or output. Many AI APIs charge separately for these categories, with output tokens often costing more. Product managers should check current pricing and estimate usage before selecting a model.
8. How are ChatGPT tokens priced?
ChatGPT subscriptions and API usage generally follow different pricing models. ChatGPT plans provide access under subscription terms, while API usage is typically billed according to the selected model and its input and output token rates.
9. Who pays for AI tokens?
For personal use through a ChatGPT subscription, the user pays the applicable subscription fee rather than a separate charge for every token. For API based applications, the developer or organisation operating the application generally pays the provider. Businesses may absorb these costs or include them in their product pricing.
10. What is the cheapest LLM to use?
The cheapest LLM depends on the task, model capabilities, and current provider pricing. Smaller models often cost less per token than advanced models, but accuracy, latency, and output quality also matter. Comparing token rates alongside performance helps teams choose a cost effective model for their needs.
1658 articles published
KnowledgeHut is an outcome-focused global ed-tech company. We help organizations and professionals unlock excellence through skills development. We offer training solutions under the people and proces...
Get Free Consultation
By submitting, I accept the T&C and
Privacy Policy